ChatTTS
Conversational text-to-speech model for natural, expressive dialogue.
Screenshots
Overview
ChatTTS is a conversational text-to-speech model built to deliver natural, expressive dialogue that closely mimics human speech. It excels at capturing the rhythm, emotion, and spontaneity of real conversation, making it perfect for interactive applications like chatting with AI characters, personal assistants, or interactive storytelling. The model understands context and adjusts its delivery accordingly, producing voices that feel alive and engaging. Whether for entertainment, education, or customer service, ChatTTS brings a human touch to voice interactions, offering developers a powerful tool to create more intuitive and empathetic user experiences.
How to Use
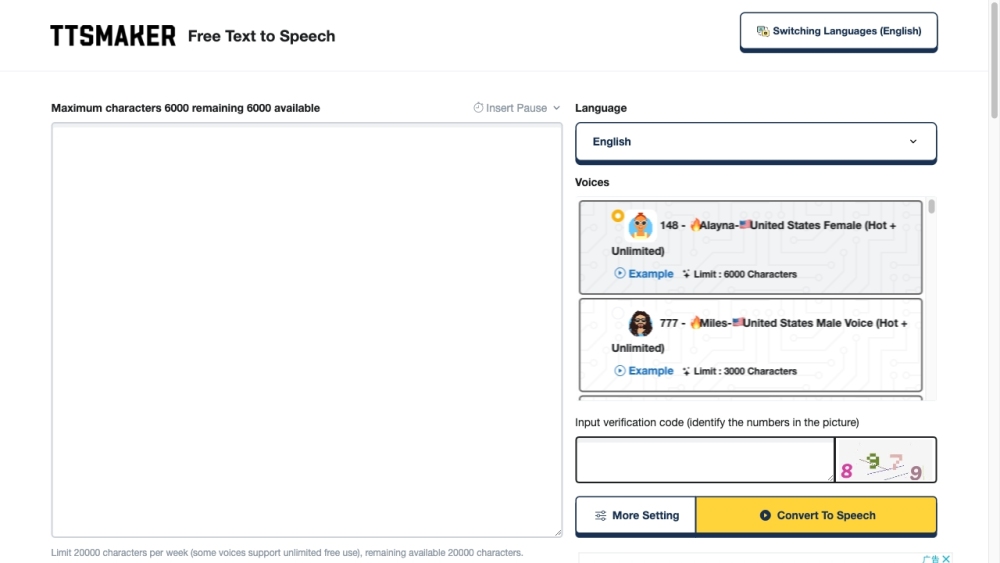
Integrate the text-to-speech model into your application or use its interface to input dialogue text. The model generates expressive, natural-sounding speech designed for back-and-forth conversation, with emotional nuance and realistic pacing. Fine-tune parameters like pitch and speed as needed.
Core Features
Use Cases
- 1 Enhancing chatbots with natural, expressive dialogue
- 2 Powering virtual assistants with lifelike speech
- 3 Research and development in text-to-speech technology
Frequently Asked Questions
ChatTTS is a conversational text-to-speech model that produces natural, expressive dialogue with controllable emotions and elements like laughter. It requires a GPU with sufficient VRAM for real-time inference, though model stability can vary.
Quick Info
- Category
- Voice Generation & Conversion
- Subcategory
- AI Voice Generator
- Added on
- Jul 11 2024
- Monthly Visits
- --
- Rating
- 5.0 / 5.0